

DistilBERT is a lightweight version of BERT (Bidirectional Encoder Representations from Transformers) developed by Hugging Face using knowledge distillation. It retains most of BERT's language understanding capabilities while reducing model size, memory usage, and computational requirements, making it suitable for resource-constrained devices and real-time NLP applications.
- Retains most of BERT's language understanding through knowledge distillation.
- Reduces the model size without significantly affecting performance.
- Enables faster inference for real-time NLP applications.
- Lowers memory and computational requirements.
Architecture
DistilBERT follows the same Transformer encoder architecture as BERT but is designed to be smaller and faster.
- Input Embeddings: The input text is tokenized and converted into dense vector representations that serve as the input to the model.
- Positional Embeddings: Positional embeddings are added to the token embeddings to preserve the order of words, allowing the model to understand the sequence of the input.
- Transformer Encoder Layers: The embedded input passes through 6 transformer encoder layers (compared to BERT's 12 layers), where contextual information is learned by capturing relationships between tokens.
- Multi-Head Self-Attention: The self-attention mechanism enables each token to attend to all other tokens in the sequence, helping the model capture contextual and semantic relationships.
- Feed Forward Network (FFN): The attention outputs are processed by a feed-forward network, which learns more informative feature representations for each token.
- Residual Connections and Layer Normalization: Residual connections and layer normalization improve training stability and ensure efficient information flow across the encoder layers.
- Contextual Output Representations: The final encoder outputs are context-aware token embeddings that are used for downstream tasks such as text classification, sentiment analysis, question answering, and named entity recognition.
Working
DistilBERT processes input text through multiple transformer encoder layers to generate contextual representations of words.
- Step 1: Input Text The process begins by providing a sentence or document as input to the model.
- Step 2: Tokenization The input text is tokenized into smaller units that can be processed by the model.
- Step 3: Embedding Generation Each token is converted into an embedding, and positional embeddings are added to preserve the order of tokens.
- Step 4: Context Learning with Self-Attention The embeddings pass through multiple transformer encoder layers, where the self-attention mechanism captures contextual relationships between tokens.
- Step 5: Knowledge Distillation During pretraining, DistilBERT learns by matching the predictions and internal representations of a larger BERT teacher model, enabling it to retain most of BERT's language understanding while using fewer layers.
- Step 6: Contextual Representations The encoder produces context-aware embeddings that capture the meaning of each token based on the entire input sequence.
- Step 7: Fine-Tuning for Downstream Tasks The learned representations are fine-tuned for tasks such as text classification, sentiment analysis, question answering, and named entity recognition.
Implementation
Let’s implement DistilBERT for a text classification task using the transformers library by Hugging Face. We’ll use the IMDb movie review dataset to classify reviews as positive or negative.
Step 1: Install Required Libraries
Install the required libraries to access the DistilBERT model, load datasets, and perform model training.
!pip uninstall -y torch torchvision torchaudio -q
!pip install -U torch -q
!pip install -U transformers datasets huggingface_hub -q
Step 2: Load the Dataset
Load the IMDb movie review dataset from the Hugging Face datasets library. The dataset contains movie reviews labeled as positive or negative.
from datasets import load_dataset

dataset = load_dataset("stanfordnlp/imdb")

train_dataset = dataset["train"]
test_dataset = dataset["test"]
Step 3: Preprocess the Data
Tokenize the reviews using the DistilBERT tokenizer to convert the text into a format suitable for the model.
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("distilbert-base-uncased")

def preprocess_function(examples):
    return tokenizer(
        examples["text"],
        truncation=True,
        padding=True,
        max_length=512
    )

tokenized_train = train_dataset.map(preprocess_function, batched=True)
tokenized_test = test_dataset.map(preprocess_function, batched=True)
Step 4: Load the Pre-trained DistilBERT Model
We’ll use the AutoModelForSequenceClassification class to load a pre-trained DistilBERT model fine-tuned for sequence classification.
from transformers import AutoModelForSequenceClassification

model = AutoModelForSequenceClassification.from_pretrained(
    "distilbert-base-uncased",
    num_labels=2
)
Step 5: Train the Model
Train the model on the training dataset using the Hugging Face Trainer API, which handles the training loop, optimization, and validation.
from transformers import Trainer, TrainingArguments, DataCollatorWithPadding

data_collator = DataCollatorWithPadding(tokenizer=tokenizer)

training_args = TrainingArguments(
    output_dir="./results",
    eval_strategy="epoch",
    learning_rate=2e-5,
    per_device_train_batch_size=16,
    per_device_eval_batch_size=16,
    num_train_epochs=3,
    weight_decay=0.01,
    logging_steps=10,
)

trainer = Trainer(
    model=model,
    args=training_args,
    train_dataset=tokenized_train,
    eval_dataset=tokenized_test,
    processing_class=tokenizer,
    data_collator=data_collator
)

train_result = trainer.train()
print(train_result)
Output:
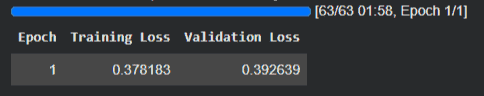
global_step =2000 ÷ 32 =63 steps, epoch = 1.0
Step 6: Evaluate the Model
Evaluate the trained model on the test dataset to measure its performance on unseen movie reviews.
results = trainer.evaluate()
print("Evaluation Results:", results)
Step 7: Make Predictions
Use the trained DistilBERT model to predict the sentiment of new movie reviews.
import torch

device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model.to(device)

new_review = "This movie was fantastic! I loved every minute of it."

inputs = tokenizer(
    new_review,
    return_tensors="pt",
    truncation=True,
    padding=True,
    max_length=512
)

inputs = {k: v.to(device) for k, v in inputs.items()}

outputs = model(**inputs)
pred = torch.argmax(outputs.logits, dim=-1)

print("Positive" if pred.item() == 1 else "Negative")
Output:
Positive
You can download the complete code from here.
Applications
- Movie Review Classification: Uses DistilBERT to quickly classify IMDB-style reviews into positive or negative sentiment.
- Real-time Chat Analysis: Applies DistilBERT in chatbots to detect user intent and respond instantly.
- Social Media Monitoring: Tracks tweets and posts to understand public opinion on brands or topics in real time.
- Email Filtering: Uses lightweight DistilBERT model to separate spam and important emails efficiently.
- Customer Feedback Mining: Extracts insights from product reviews for improving services in e-commerce platforms.
- Lightweight NLP Deployment: Used in mobile and edge applications where fast inference and low memory are required.
Advantages
- Smaller model size makes it easier to deploy in real systems.
- Faster inference suitable for real-time text processing tasks.
- Lower GPU/CPU usage during training and prediction.
- Works well even on limited hardware like mobile or edge devices.
Limitations
- Slight drop in accuracy compared to full BERT models.
- Less effective for highly complex NLP tasks requiring deep reasoning.
- Limited capacity due to fewer transformer layers.
- Performance depends heavily on quality of fine-tuning data.
- Not ideal for tasks needing very long context understanding.
BERT vs. DistilBERT
| Feature | BERT | DistilBERT |
|---|---|---|
| Model Size | Larger (~110M parameters) | Smaller (~66M parameters) |
| Layers | 12 layers | 6 layers |
| Speed | Slower | Faster |
| Memory | Higher memory usage | Lower memory usage |
| Performance | Generally higher | Close to BERT |
| Deployment | Resource-intensive applications | Resource-constrained applications |